|
I am a third-year PhD student in the Computer Science Department at Stanford University advised by Marco Pavone and Clark Barrett. I received my Bachelor of Science (2020-2023) and Master of Science (2023-2024) in Computer Science at UC San Diego, where I was advised by Sicun Gao and Sylvia Herbert. My interests are in multimodal reasoning and out-of-distribution (OOD) generalization for robotics. Contact: mganai at cs dot stanford dot edu |
|
|
DIRECTroutes per subgoal — thinks only on the hard pick
planning… 20.5s planning · ✓ correct order
planning (fast)
thinking
|
Jadelynn Dao➤, Milan Ganai➤, Yasmina Abukhadra, Ajay Sridhar, Mozhgan Nasr Azadani, Katie Luo, Clark Barrett, Jiajun Wu, Chelsea Finn, Marco Pavone CoRL 2026 Conference on Robot Learning arxiv | website FM4RoboPlan@RSS 2026 — Workshop on Robot Planning in the Era of Foundation Models in Robotics: Science and Systems ★ Oral Presentation ★ Vision-Language Models are increasingly used as high-level planners for embodied agents, and the default recipe for improving them is to scale test-time compute like chain-of-thought reasoning, bigger models, more memory history. In robotics, that compute is not free: it adds latency, tokens, and FLOPs while delivering uneven, often diminishing returns. DIRECT is a lightweight routing framework that uses multimodal scene context to decide when and where to spend test-time compute, learning a mapping from a task's scene and instruction to the planner best suited to solve it, matching high test-time-compute-level success at a fraction of the planning time. ➤equal contribution |
|
Milan Ganai♫, Katie Luo♫, Jonas Frey, Clark Barrett, Marco Pavone RSS 2026 Robotics: Science and Systems arxiv | code | models | website | SAIL blog Embodied Chain-of-Thought (CoT) reasoning has enhanced Vision-Language-Action (VLA) models, but rigid templates over reasoning primitives (objects, plans, affordances) force policies to process irrelevant information that distracts from action-prediction signals. We introduce R&B-EnCoRe, which treats reasoning as a latent variable within importance-weighted variational inference, enabling models to bootstrap embodiment-specific reasoning from internet-scale knowledge through self-supervised refinement — without external rewards, verifiers, or human annotation. Validated across manipulation, legged navigation, and autonomous driving with various VLA architectures with 1B, 4B, 7B, and 30B parameters. ♫equal contribution |
|
|
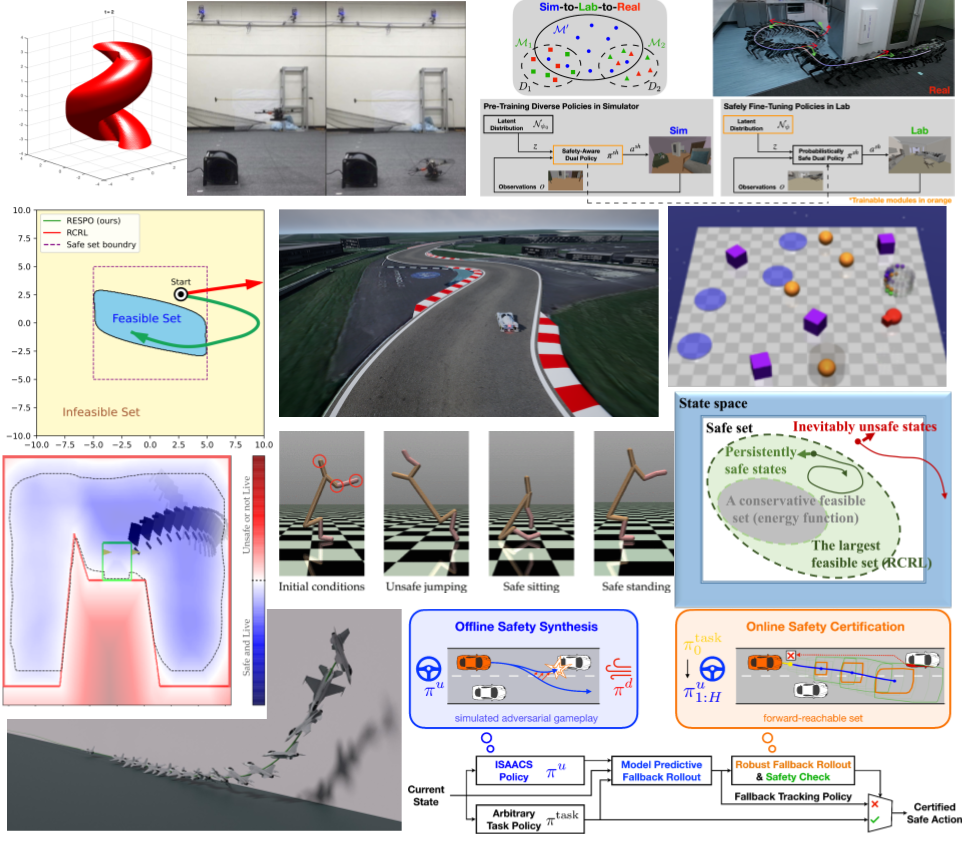
Milan Ganai, Rohan Sinha, Christopher Agia, Daniel Morton, Luigi Di Lillo, Marco Pavone CoRL 2025 Conference on Robot Learning ★ Oral Presentation ★ arxiv | website As autonomous systems expand their deployment regions into unstructured, open-world environments, they face potential hazardous Out-of-Distribution (OOD) failure scenarios that differ from their training data. Current methods rely on handcrafted intervention policies, limiting their ability to plan generalizable, safe motions. FORTRESS introduces a novel framework that generates and reasons about semantically safe fallback strategies in real time to prevent OOD failures by bridging open-world, multi-modal reasoning with dynamics-aware planning. |
|
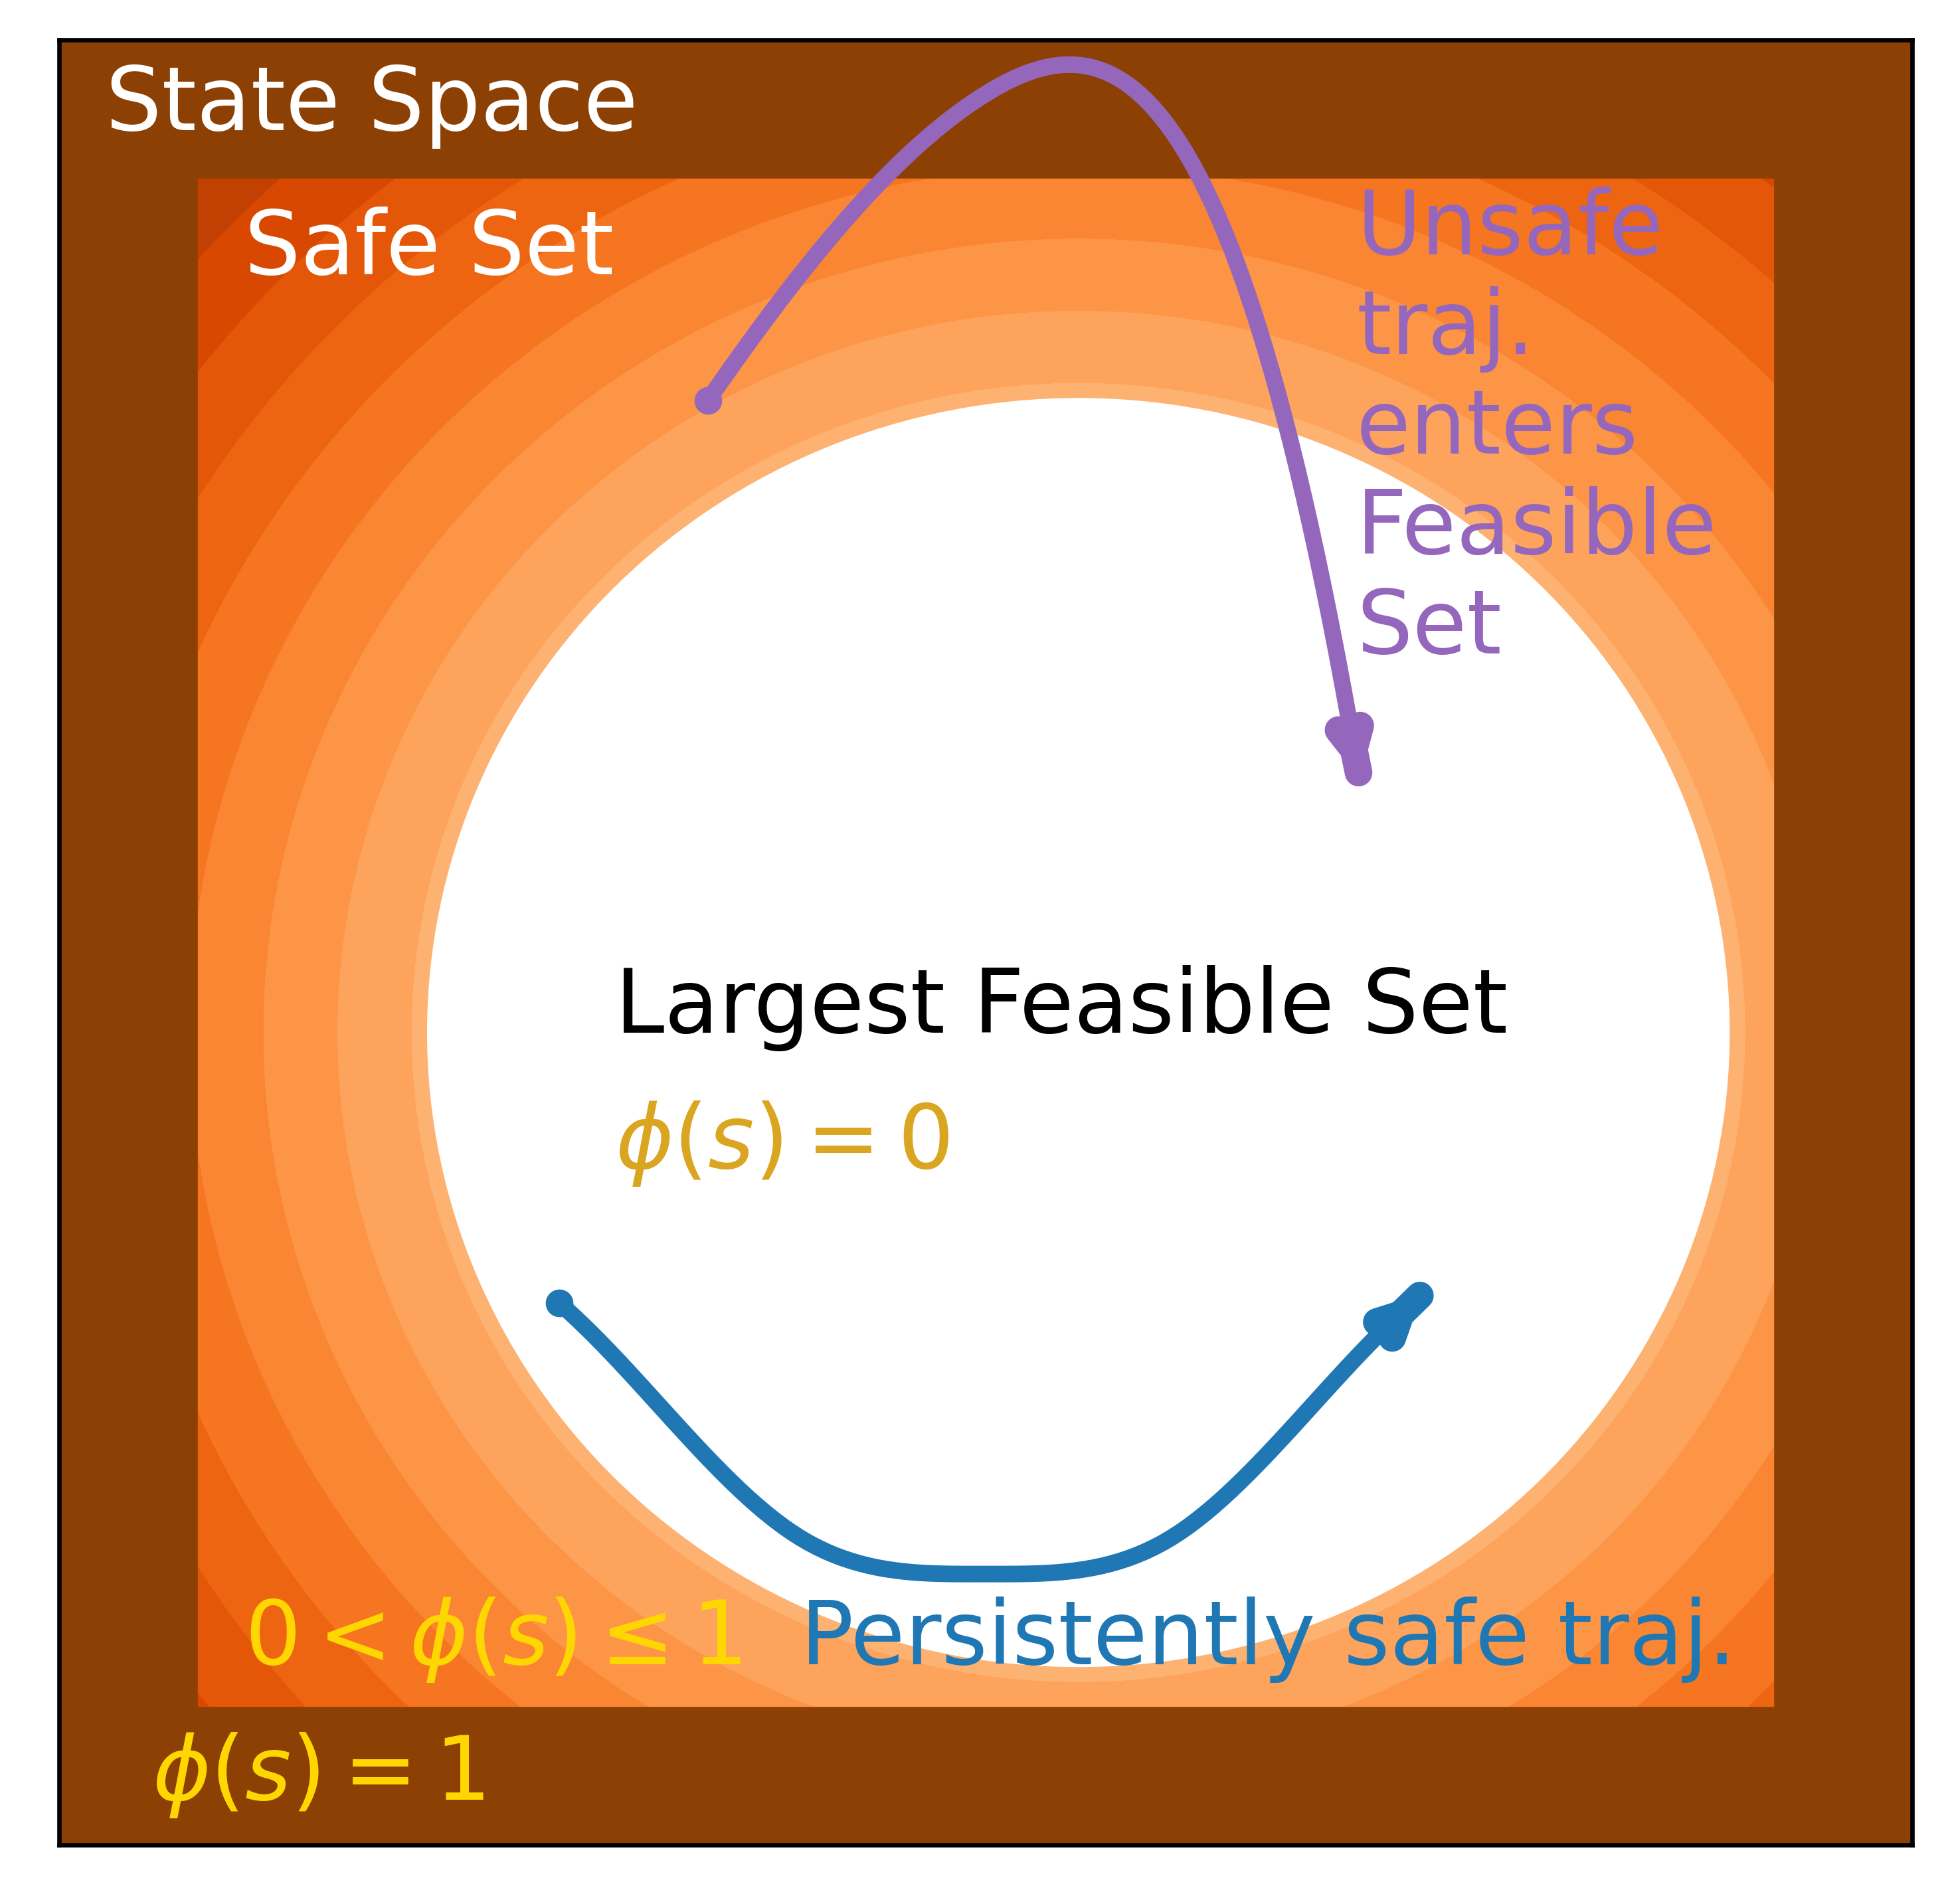
Milan Ganai, Sicun Gao, Sylvia Herbert OJ-CSYS 2024 IEEE Open Journal of Control Systems arxiv | IEEE (Open Access) A journal publication surveying the recent literature on scalable Hamilton-Jacobi reachability estimation in reinforcement learning to provide a foundational basis for research into reliability in high-dimensional systems. We review how this technique has been employed to solve challenging tasks like those with dynamic obstacles and lidar-based or RGB image-based observations. |
|
Milan Ganai, Zheng Gong, Chenning Yu, Sylvia Herbert, Sicun Gao NeurIPS 2023 Conference on Neural Information Processing Systems paper | openreview | code | website Hamilton-Jacobi reachability estimation for model-free safe RL in deterministic and stochastic environments with safety guarantees and convergence analysis. Tasks include lidar-based observations, dynamic obstacles, and multiple hard and soft constraints. |
|
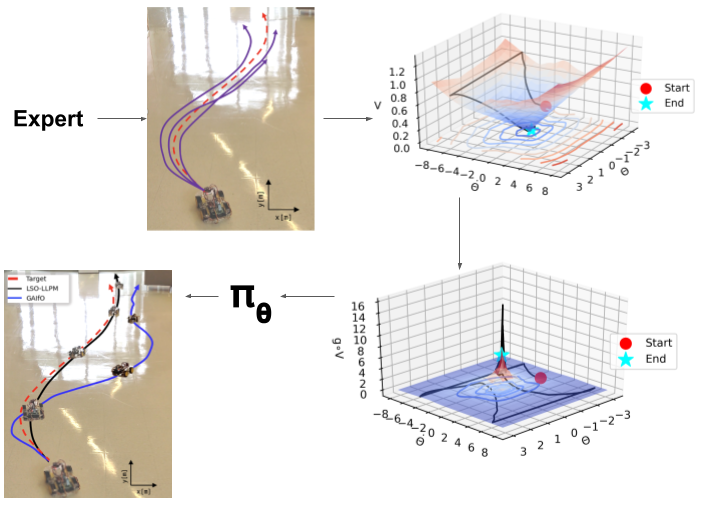
Milan Ganai, Chiaki Hirayama, Ya-Chien Chang, Sicun Gao ICRA 2023 IEEE International Conference on Robotics and Automation paper | IEEE | website Learning Lyapunov-like models offline from observation-only, expert data to solve stabilization control tasks online. Deployed in hardware for robustness testing. |
|
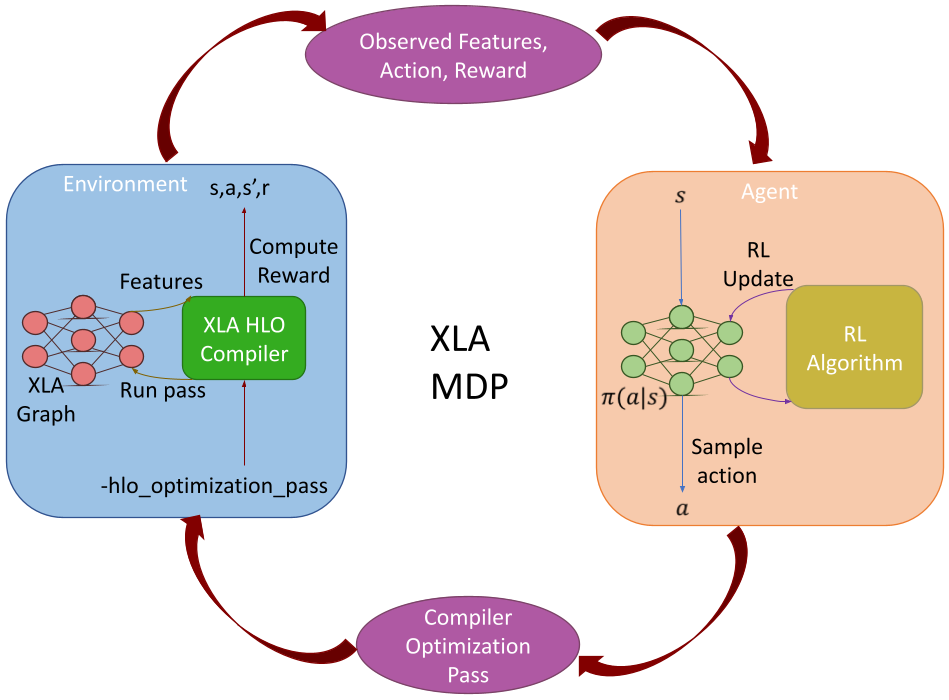
Milan Ganai, Haichen Li, Theodore Enns, Yida Wang, Randy Huang ML for Systems @ NeurIPS 2022 — Workshop on ML for Systems in Neural Information Processing Systems paper | website Reinforcement Learning to determine XLA compiler optimization pass ordering to reduce GPT-2, BERT, and ResNet graph sizes. |
|
Patrick McCormack, Milan Ganai, Ben Nachman, Maurice Garcia-Sciveres CTD/WIT 2019 — Connecting the Dots / Workshop on Intelligent Trackers paper Building boosted decision trees to classify reconstructed particle tracks as merged in high density particle physics environments. |
|
|